 By
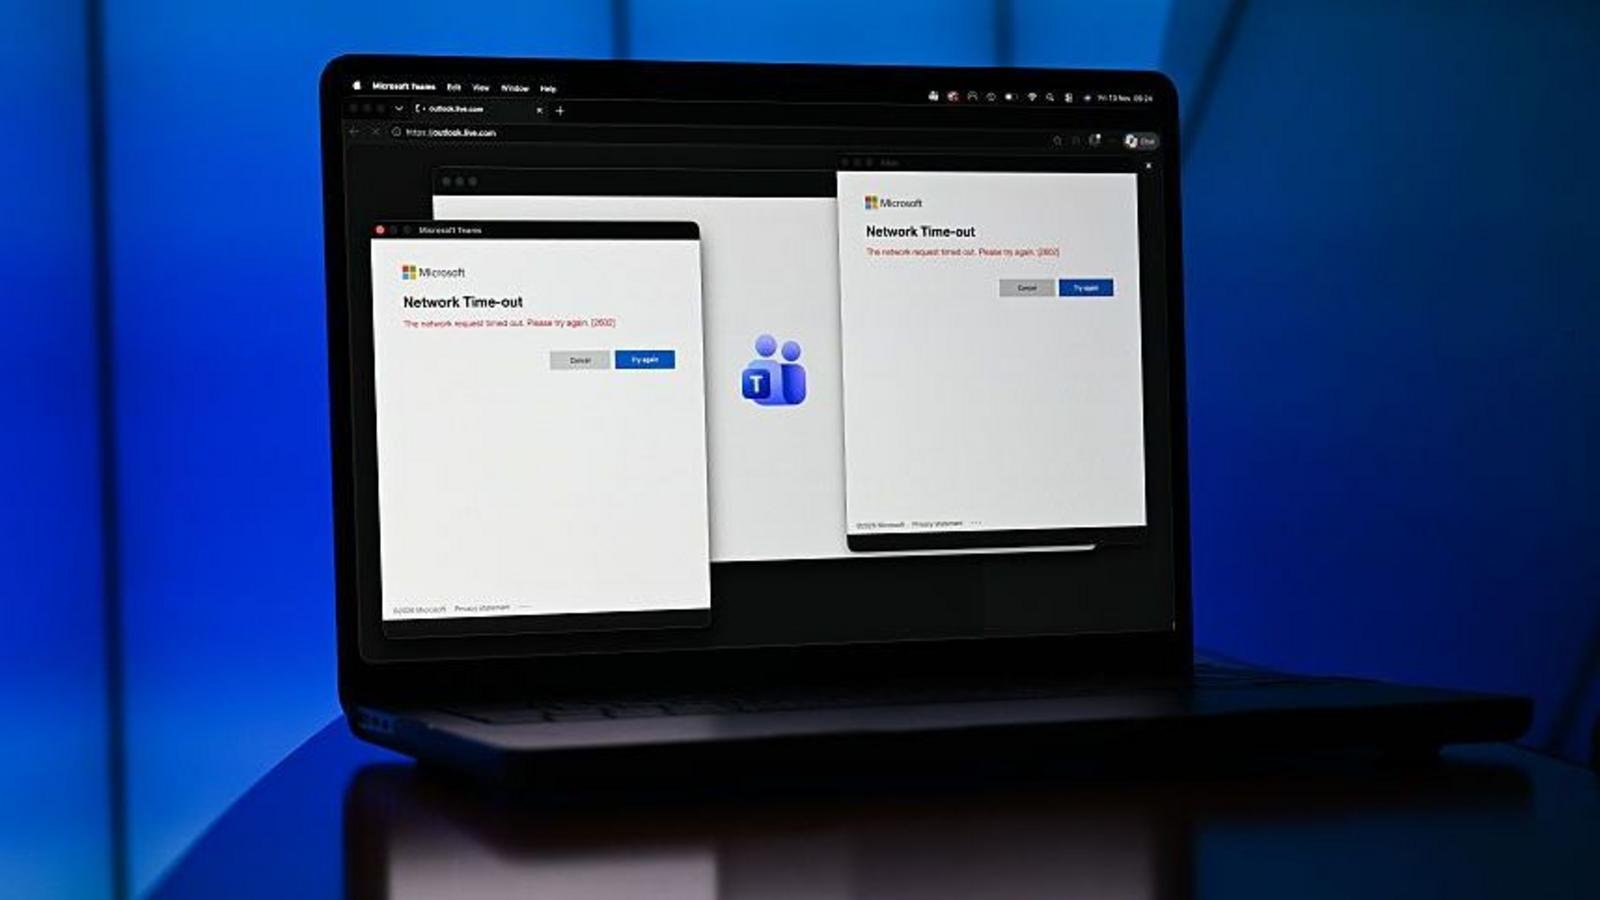
Technology giant Microsoft has officially confirmed that service functionality across its flagship enterprise portfolio—including Microsoft Teams, Outlook, and AI-driven Copilot tools—has been fully restored following a prolonged global outage. The day-long disruption crippled corporate communications, financial transactions, and operational workflows across multiple continents, reigniting intense international debate over systemic concentration risks within public cloud infrastructure.
Strategic Background & Global Timeline
The operational crisis began in the early hours of the morning when telemetry data indicated widespread connectivity failures across Microsoft Azure and 365 services. Corporate networks from London to Tokyo reported immediate access degradation, leaving corporate teams unable to send emails, initiate video conferences, or access critical stored data. Initial diagnostics pointed to unexpected routing anomalies and configuration failures within Microsoft’s core networking framework, which cascadingly impaired authentication protocols worldwide.
As the day progressed, enterprise IT departments were forced into crisis management modes, deploying legacy offline backup channels or temporary third-party messaging tools to maintain essential operational continuity. The disruption severely affected multinational banks, healthcare networks, logistics nodes, and government offices that rely on Microsoft’s cloud ecosystem as their central operational nervous system.
Verified Technical Remediation & Engineering Intervention
Engineers at Microsoft executed a series of complex mitigation maneuvers to isolate the root cause, which engineers traced back to a faulty routing update that disrupted internal traffic pathways across key data centers. To stabilize the network, technical teams rerouted global traffic through healthier infrastructure channels while rolling back recent system updates. Throughout the multi-hour engineering intervention, Microsoft published periodic telemetry updates promising steady incremental recovery.
By late evening, the Redmond-based corporation declared that underlying technical issues had been completely resolved. Systems engineers confirmed that all major services, including Outlook mail delivery, Teams collaborative calling, and Copilot productivity modules, were functioning at normal baseline parameters. Microsoft noted that comprehensive post-incident reviews are currently underway to audit the failure modes and fortify core infrastructure against similar cascading events.
“This global event underscores the acute structural fragility of modern enterprise architecture when central cloud services encounter unexpected failure modes. Diversity of infrastructure is no longer a luxury; it is a fundamental pillar of national economic resilience.”
Economic Impact & Enterprise Vulnerabilities
Market analysts estimate that the financial cost of the day-long outage across affected enterprise clients could reach hundreds of millions of dollars in lost productivity, delayed transactions, and emergency mitigation expenses. Trading desks experienced brief transactional delays, while logistical fulfillment centers reported scheduling backlogs as automated scheduling scripts tied to Microsoft 365 environments stalled.
The incident has intensified scrutiny from enterprise risk officers and international regulatory bodies. Organizations that consolidated their IT stacks into single-vendor public clouds now face renewed questions from shareholders regarding single-point-of-failure vulnerabilities. Industry experts emphasize that while cloud efficiency is unassailable, operational over-reliance without adequate multi-cloud redundancy creates immense macroeconomic vulnerability.
Key Takeaways & Strategic Intelligence
- Full System Recovery: Microsoft has officially resolved all technical impairments affecting Outlook, Teams, and Copilot, restoring standard global operations.
- Network Routing Origin: The outage was catalyzed by routing anomalies and configuration updates within central backend network infrastructure.
- Severe Productivity Impact: Multinational corporations, financial services, and healthcare facilities experienced broad operational delays during the 24-hour disruption.
- Heightened Regulatory Focus: International regulators are expected to increase compliance scrutiny regarding operational resilience and multi-cloud redundancies for critical industries.
Regulatory Scrutiny & Sovereign Cloud Imperatives
The outage is poised to accelerate regulatory initiatives across Europe and North America aimed at enforcing stricter operational resilience standards for cloud service providers. European Union tech regulators are expected to review the incident under the framework of recent digital operational resilience guidelines, which mandate robust disaster recovery mechanisms for critical tech providers supporting financial and public services.
Furthermore, discussions around sovereign cloud solutions and localized data infrastructure are likely to regain momentum among national security officials. Governments worldwide are increasingly viewing hyper-concentrated cloud environments as critical national infrastructure, demanding higher operational transparency, mandatory failure reporting, and independent system audits.
Future Outlook & Strategic Projections
As Microsoft works to issue its comprehensive post-incident root cause analysis, corporate IT directors worldwide are reassessing their digital resiliency strategies. Analysts anticipate an uptick in enterprise investments focused on multi-cloud architectures, secondary fallback systems, and enhanced local offline operational capacity. While Microsoft’s swift engineering response stabilized the immediate crisis, the broader lesson for global commerce is clear: mitigating cloud concentration risk will be a defining imperative for enterprise security over the coming decade.